Voice AI in India: The 800 ms Budget Most Demos Ignore
A voice AI demo in a quiet room proves very little. Production voice AI in India has to survive code-mixed speech, noisy phone lines and a tight response budget. Here is a practical latency budget, the failure modes that matter, and a test plan you can run before you sign a vendor.
By Vikas Goel
A voice AI demo in a quiet room proves very little. The speaker is clear, the question is expected, and nobody is calling from a moving auto.
I've shipped enterprise voice AI used by millions and led MagicCall, a consumer voice app with 14M+ downloads. The lesson I keep coming back to is simple: voice systems fail in the seams between components, and India is very good at finding those seams.
The budget
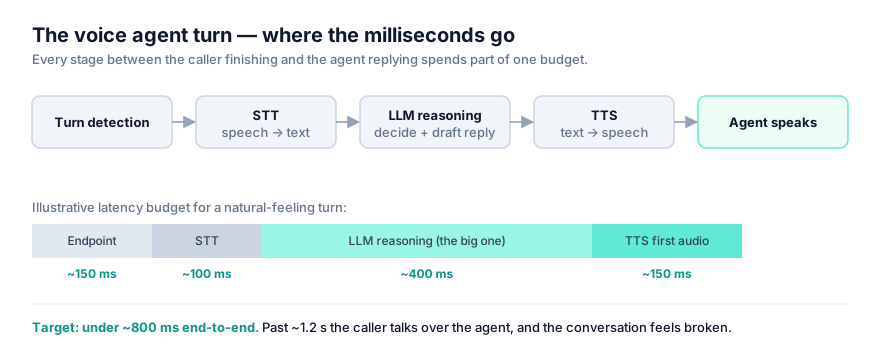
Pick a number before you pick a vendor. I plan around 800 ms from the end of the caller's sentence to the first audio of the reply. This is a planning budget, not a benchmark result, so replace each line with your own measurements.
| Stage | Budget |
|---|---|
| Detect that the caller has finished | 150 ms |
| Speech-to-text | 100 ms |
| Model reasoning and first useful tokens | 400 ms |
| Text-to-speech first audio | 150 ms |
| Total | 800 ms |
Now add one database lookup or a slow tool call. The budget is gone. That is why latency has to be an architecture decision and can't be left as a tuning task for the last week.
What breaks on real Indian calls
- Code-mixed speech. One sentence can move between Hindi and English, or between a regional language and English. A language setting chosen at the start of the call won't handle that.
- Names and numbers. A small transcription error in a sentence is forgiven. A wrong digit in an account number is not.
- Line quality. Compressed audio and background noise hurt transcription and also the detection of when someone has stopped talking.
- Interruptions. People talk over the agent. If it can't stop quickly, it feels broken however good the model is.
The test plan
Don't ask a vendor for their accuracy number. Bring your own calls, recorded with consent, and score every vendor on the same set.
| Measure | Why it matters |
|---|---|
| Accuracy on names and numbers | These errors cause real damage |
| Task completion | The only outcome the business cares about |
| 95th-percentile response time | Averages hide the worst calls |
| Barge-in stop time | Decides whether it feels like a conversation |
| Correct escalation rate | Handing over is often the right answer |
Run clean audio and difficult audio separately. A vendor that looks excellent overall can still fall apart on the calls you most need to handle.
Where the facts should come from
India now has serious local options, including the models and voice stacks shown at the India AI Impact Summit. A better model still won't remove the most expensive failure: a confident wrong answer about a balance, a policy or a price.
So let the model handle language and conversation, and pull facts from a system of record. I wrote about the pattern in the deterministic AI agents guide and in voice AI hallucination in regulated industries.
Vikas Goel is the founder of Thinkerwave AITech and a former enterprise CTO. He works with enterprises and founders as a fractional AI CTO and voice AI consultant.
- Voice AI India
- Voice AI
- Conversational AI
- AI Voice Agents
- Hindi Voice AI